Regulated AI workloads need infrastructure designed around data movement, access boundaries, operational evidence, and recovery, not only GPU capacity. A well-designed AI infrastructure stack connects each production workload to controls that the organization can test and document. For Brazilian banks, fintechs, and other regulated companies, that also means deciding where data is processed and how provider responsibilities fit existing governance.
Key design decisions for regulated AI
- Map every data flow, including prompts, logs, embeddings, backups, and support access.
- Match GPU capacity and storage performance to the model’s actual workload.
- Use orchestration to apply isolation, access, and resource policies consistently.
- Define evidence, incident response, and recovery requirements before production.
- Measure cost and service quality per completed workload, not just per GPU hour.
Start with the workload and its data boundary
The first design decision is which data the application processes and where each part of that data travels. A customer-service model, for example, may receive personal information in prompts, retrieve internal records, create embeddings, and write request logs. Those are separate flows with different access, retention, and location requirements.
Teams should map the path from source system to model and back, including backups, monitoring tools, and human support. They can then classify data, identify who can access it, and specify where processing and storage are permitted. Keeping compute and data in Brazil can reduce cross-border exposure, but location alone does not establish LGPD compliance.
The ANPD’s international transfer regulation sets conditions and valid mechanisms for transfers of personal data. A design should therefore record whether a transfer occurs and which legal mechanism applies, rather than treating every transfer as automatically prohibited or automatically compliant.
Build the stack around six operational layers
A production stack works when each layer has a clear owner, boundary, and testable control. The following view connects technical components to the evidence that risk and platform teams need.
| Layer | Design focus | Useful evidence |
|---|---|---|
| Workload | Model, task, users, and permitted actions | Approved use case and access policy |
| Data | Sources, storage, retention, and movement | Data-flow map and retention rules |
| Compute | GPU, CPU, memory, and capacity | Benchmark and capacity records |
| Orchestration | Scheduling, isolation, and deployment | Configuration and deployment history |
| Security | Identity, secrets, network, and encryption | Access reviews and security tests |
| Operations | Monitoring, incidents, and recovery | Alerts, incident records, and recovery tests |
This structure also helps teams compare infrastructure providers on concrete requirements: deployment geography, workload isolation, contract terms, support access, and recoverability. A provider checklist is more useful when each item is tied to a control or evidence artifact, rather than a broad claim of security.
Size GPU capacity for the model’s actual behavior
GPU selection should follow measured workload needs, not model size alone. Inference traffic, fine-tuning jobs, and agent workflows place different demands on memory, concurrency, storage throughput, and response time. An agent that calls tools repeatedly, for instance, may create a different request pattern from a single-response chat interface.
Before choosing capacity, teams should benchmark representative inputs and expected concurrency. They should record response latency, throughput, memory use, queue time, and failure behavior under load. These tests reveal whether the bottleneck sits in GPU memory, CPU preprocessing, storage reads, or the application’s own request handling.
Production sizing should also include a capacity policy. Teams can define when workloads queue, when additional GPU capacity is provisioned, and how non-urgent jobs yield to customer-facing inference. This avoids reserving expensive accelerators for workloads that do not need immediate execution, while protecting service levels for critical requests.
Use Kubernetes to make workload boundaries repeatable
Kubernetes can provide a consistent control plane for deploying models and allocating GPU resources, provided the cluster is configured to expose and govern those devices correctly. Its device plugin framework lets vendor-specific resources such as GPUs be advertised to the kubelet for scheduling.
For regulated workloads, GPU scheduling is only one part of the design. Teams should define namespace and service-account boundaries, role-based access, network policies, secret handling, resource quotas, and deployment approvals. These controls should be tested against the actual paths between the application, model server, data stores, and monitoring systems.
Model artifacts and configuration changes also need traceability. Versioned deployments, controlled access to model registries, and rollback procedures help teams identify what changed when outputs or performance shift. For agent-based applications, tool permissions should be separated from model access so that a generated response does not automatically gain authority to perform sensitive actions.
Make compliance, audit, and recovery part of the architecture
Regulatory and contractual requirements should shape the service design before workloads go live. For institutions within its scope, CMN Resolution 4,893 addresses contracting for relevant data processing, storage, and cloud services, including the countries and regions where services and data may be located, data segregation, security, incidents, and continuity.
That makes provider and platform documentation operationally important. Contracts and runbooks should clarify permitted locations, support access, incident notification, data return or deletion, service interruption procedures, and how the organization can restore or move its workload. Recovery plans should specify tested recovery objectives and dependencies, including model files, container images, credentials, and source data.
A risk framework can help connect technical controls to ownership and review. NIST describes its AI Risk Management Framework as a voluntary resource for managing AI risks, including risks specific to generative AI. Teams can use it as a planning reference alongside Brazilian legal and sector-specific obligations, not as a substitute for them.
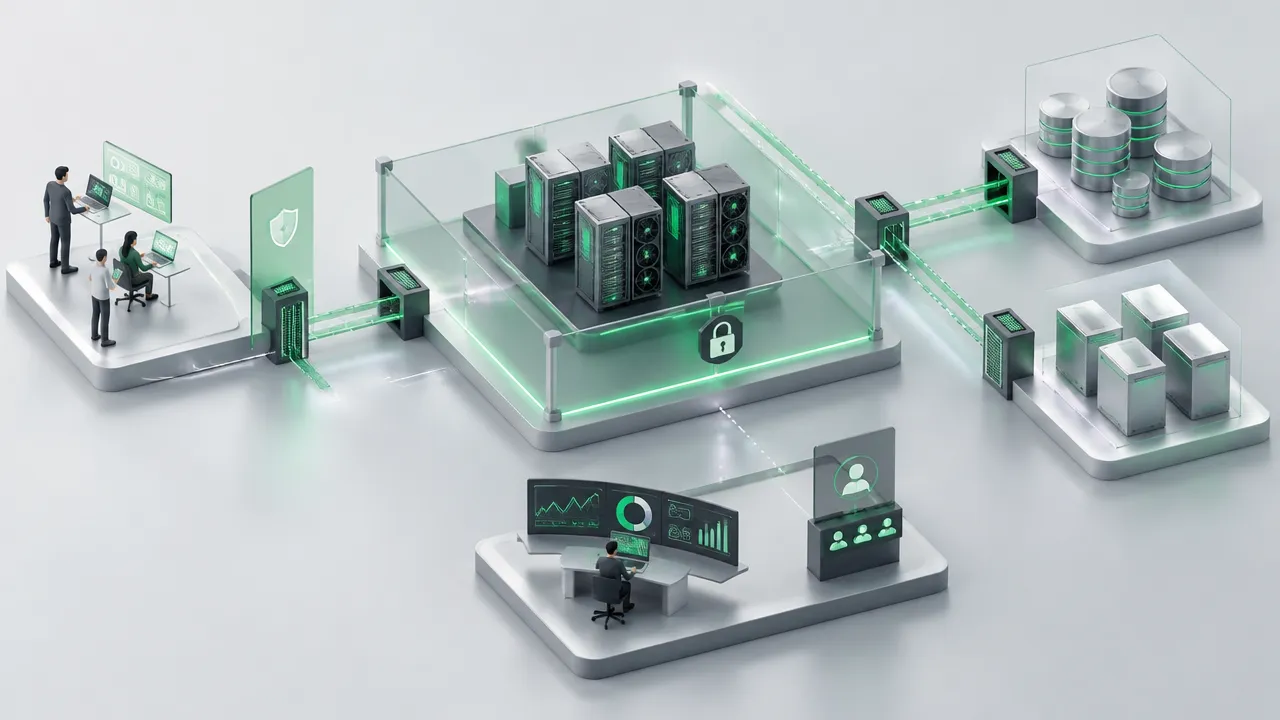
Track service quality and cost at the workload level
A useful operating model measures whether each workload meets its service and governance objectives. Teams should monitor request latency, queue depth, error rates, GPU utilization, capacity availability, and the health of dependent data services. They should also define who receives alerts and what actions follow when a threshold is breached.
Cost analysis should include more than the GPU rate. Storage, data movement, idle capacity, support, and recovery arrangements can all affect the total cost of a production service. Measuring cost per successful request or completed batch makes it easier to compare deployment options and set budgets as usage changes.
For Brazilian workloads, billing currency, tax documentation, data location, and egress terms can also affect procurement and operations. Nuplia provides managed GPU-as-a-Service in Brazil, with elastic, hourly billed NVIDIA GPU capacity, including RTX PRO 6000 Blackwell GPUs, Kubernetes and GPU orchestration, Portuguese-language contractual support, BRL invoicing with NF-e, and zero egress fees. Those capabilities can be assessed against the workload’s technical and governance requirements.
Launch with a controlled production path
A staged rollout exposes design gaps before a model becomes a critical dependency. A pilot should use representative data and traffic, apply the intended security boundaries, and exercise monitoring and recovery procedures. Teams should capture baseline performance and cost so later changes can be evaluated against a known operating state.
- Document the use case, data classes, and approved locations.
- Benchmark the model with representative inputs and concurrency.
- Test identity, network, storage, and GPU isolation controls.
- Run incident, rollback, and recovery exercises.
- Review service evidence, cost, and ownership before expanding traffic.
This approach gives engineering, security, compliance, and procurement teams a shared basis for decisions. The resulting AI infrastructure stack is easier to audit and adapt because its boundaries, dependencies, and operating evidence are designed alongside the application.